BelvedereMeet Belvedere:

Your Agentic Data Manager

Declare what data you need. Belvedere handles everything behind it: discovery, governance, pipeline generation, observability, and repair across your existing stack, with deterministic results your teams can verify and trust.

You define the goal. Belvedere engineers the solution.

Describe the data products you need in plain, goal-oriented terms. Belvedere's agents harness AI speed and intelligence to derive contracts, reason through system models, and generate deterministic, repeatable implementations you can verify and trust — delivering in minutes, not the weeks or months you're used to waiting.

  • Plain-language in, deterministic code out — no hallucinations
  • Every output is verifiable, repeatable, and auditable
  • AI speed without sacrificing trust or control
  • Minutes to production, not weeks
app.clearfracture.ai/pipelines/logistics-monitoring
Live
Global Logistics MonitoringUnsaved
Source

Carrier Tracking Systems

Source

Warehouse Management Suite

Source

Customs & Compliance Feeds

Transform

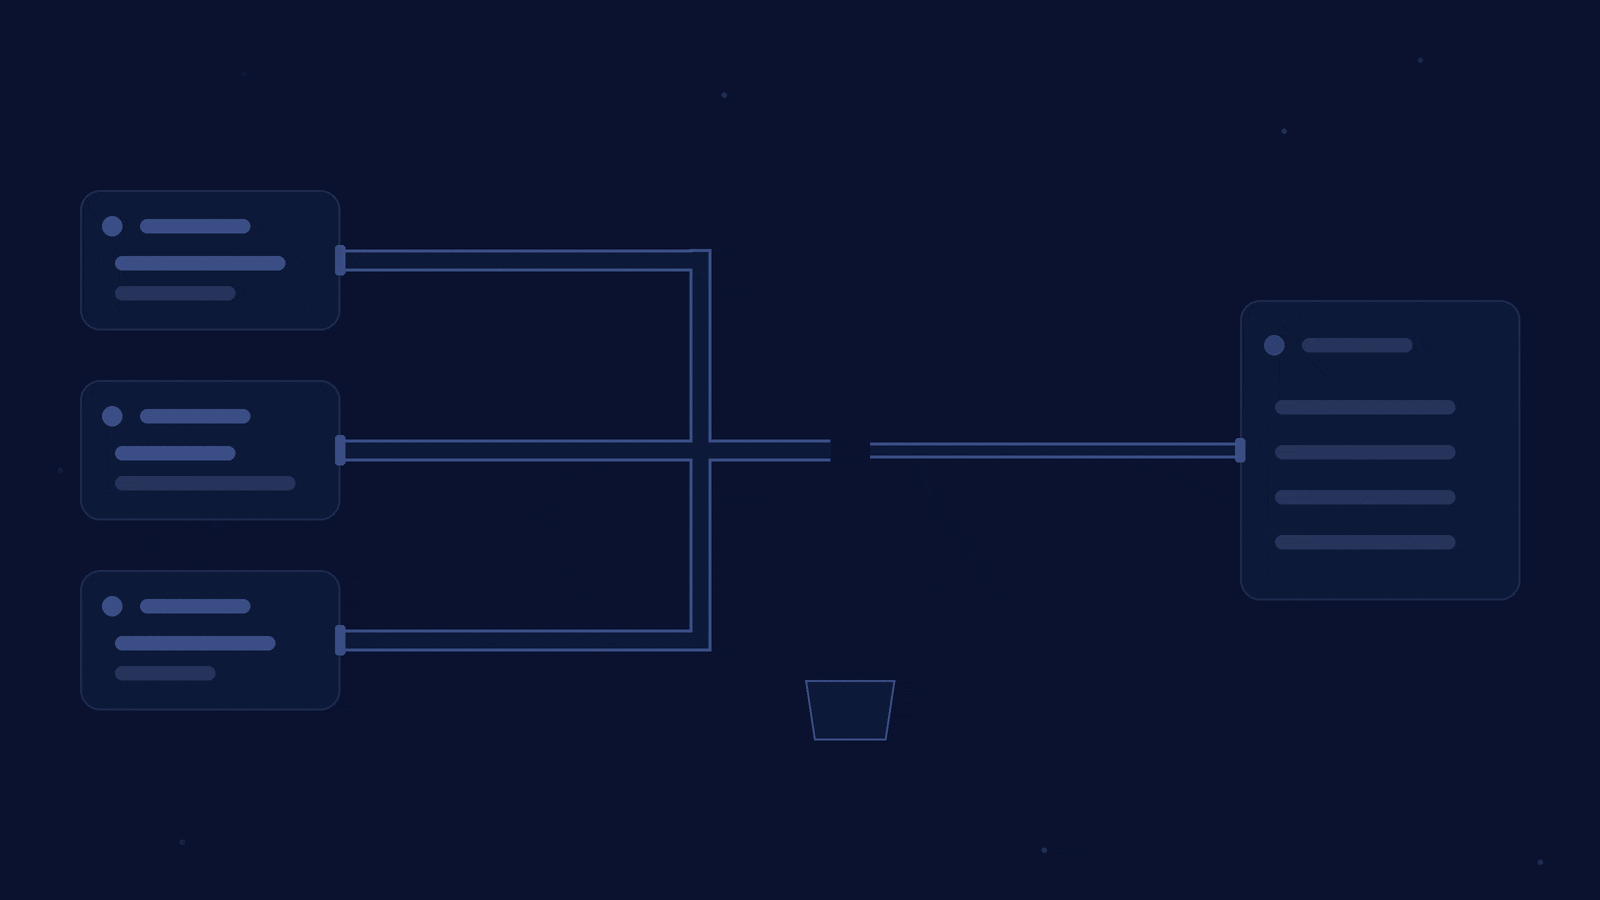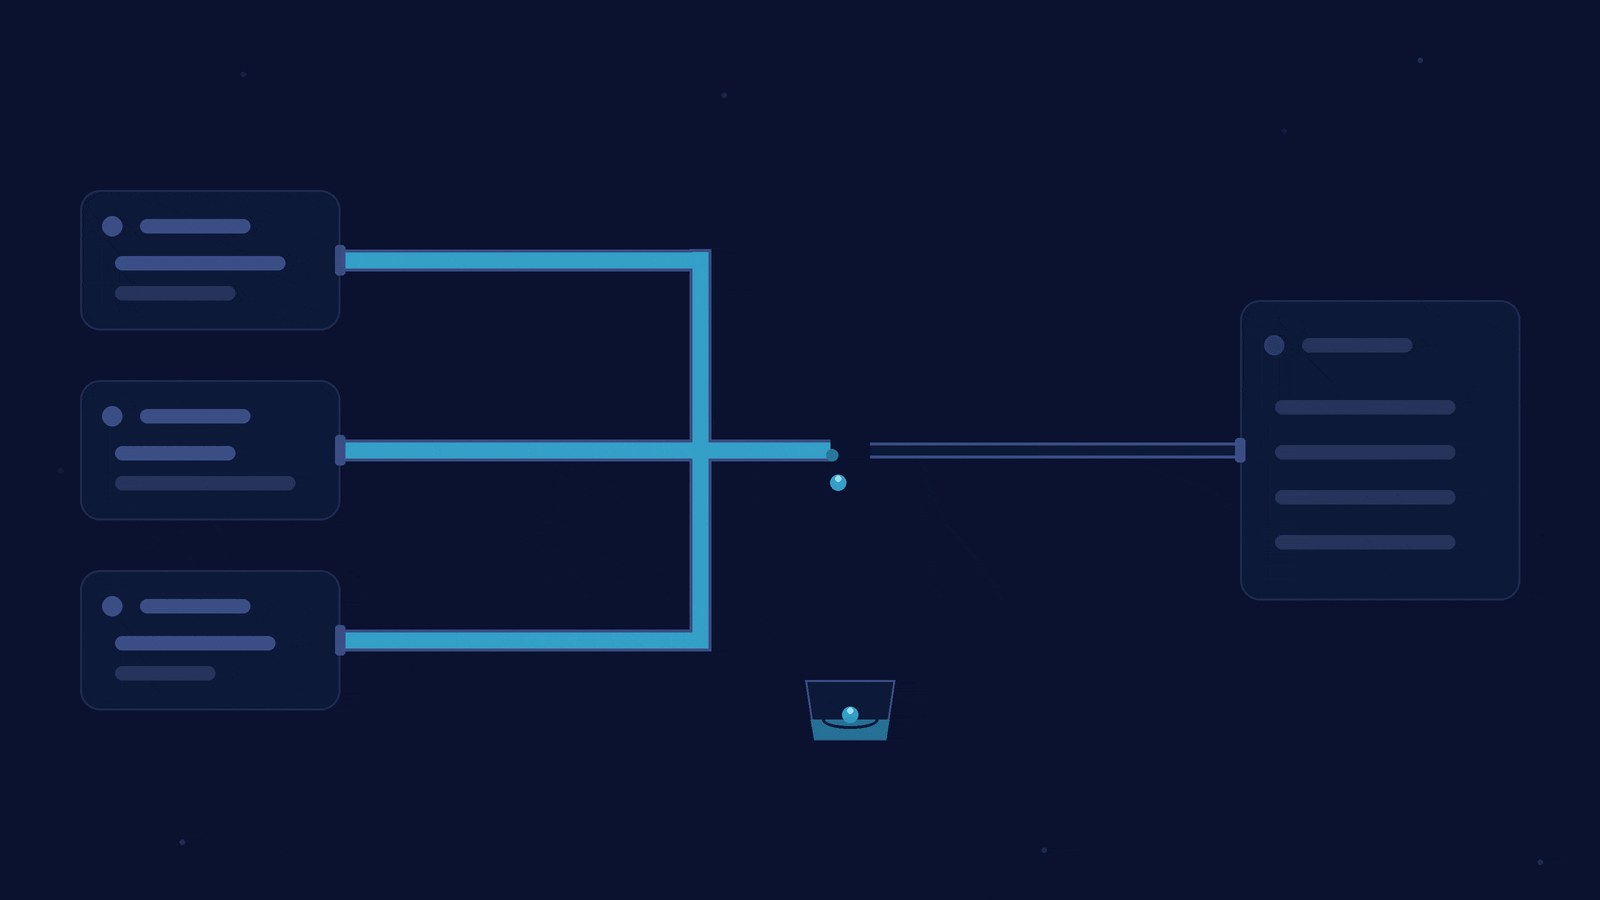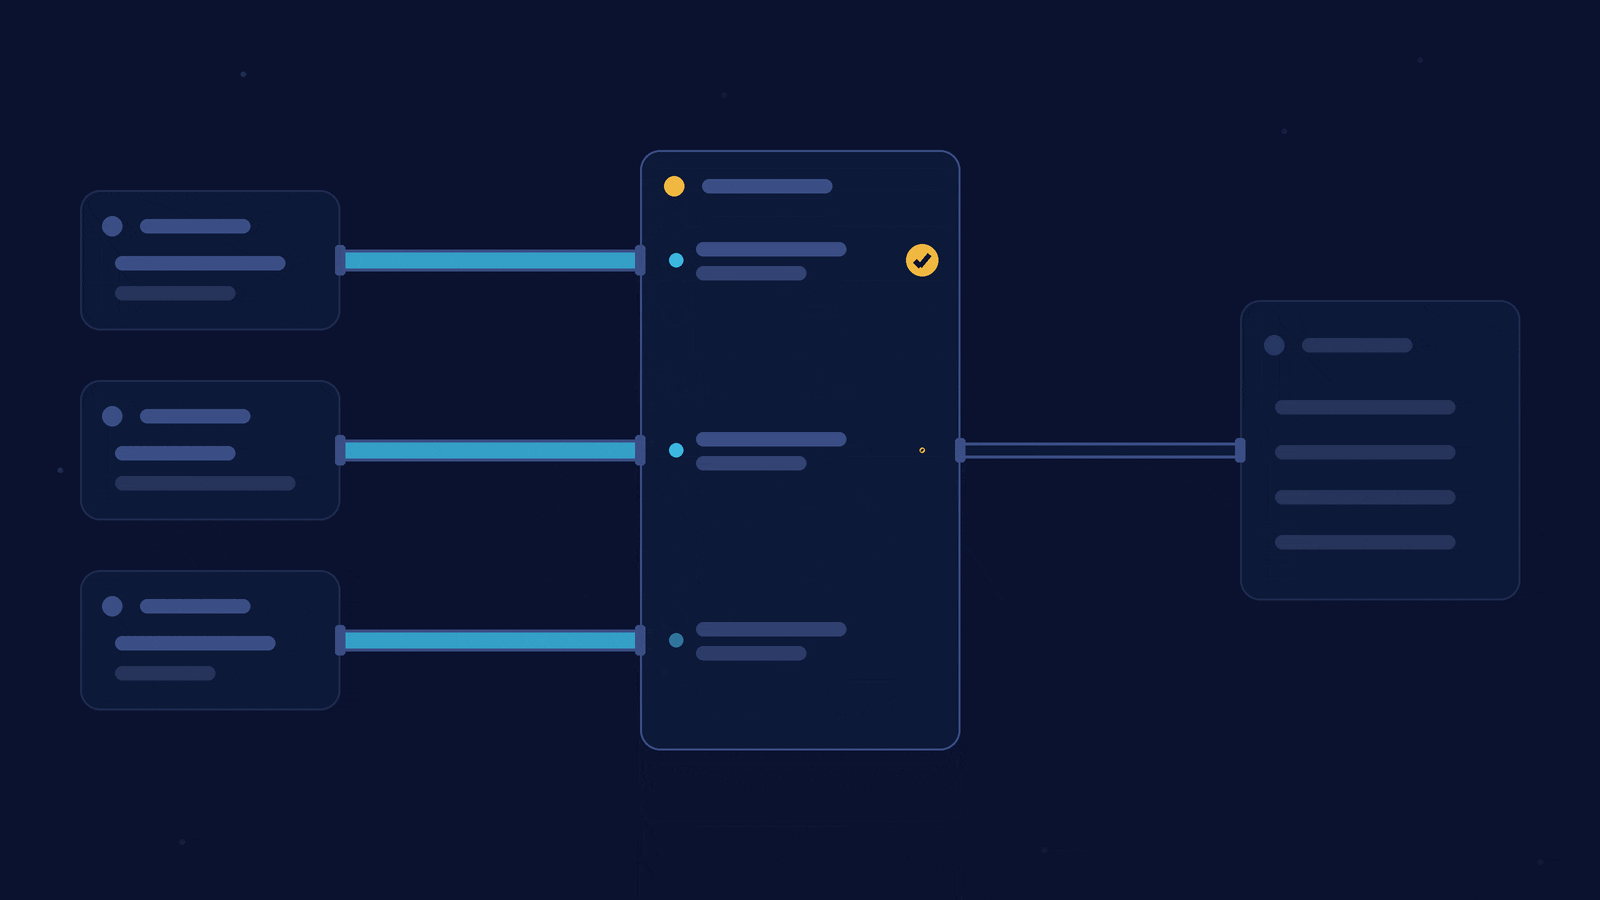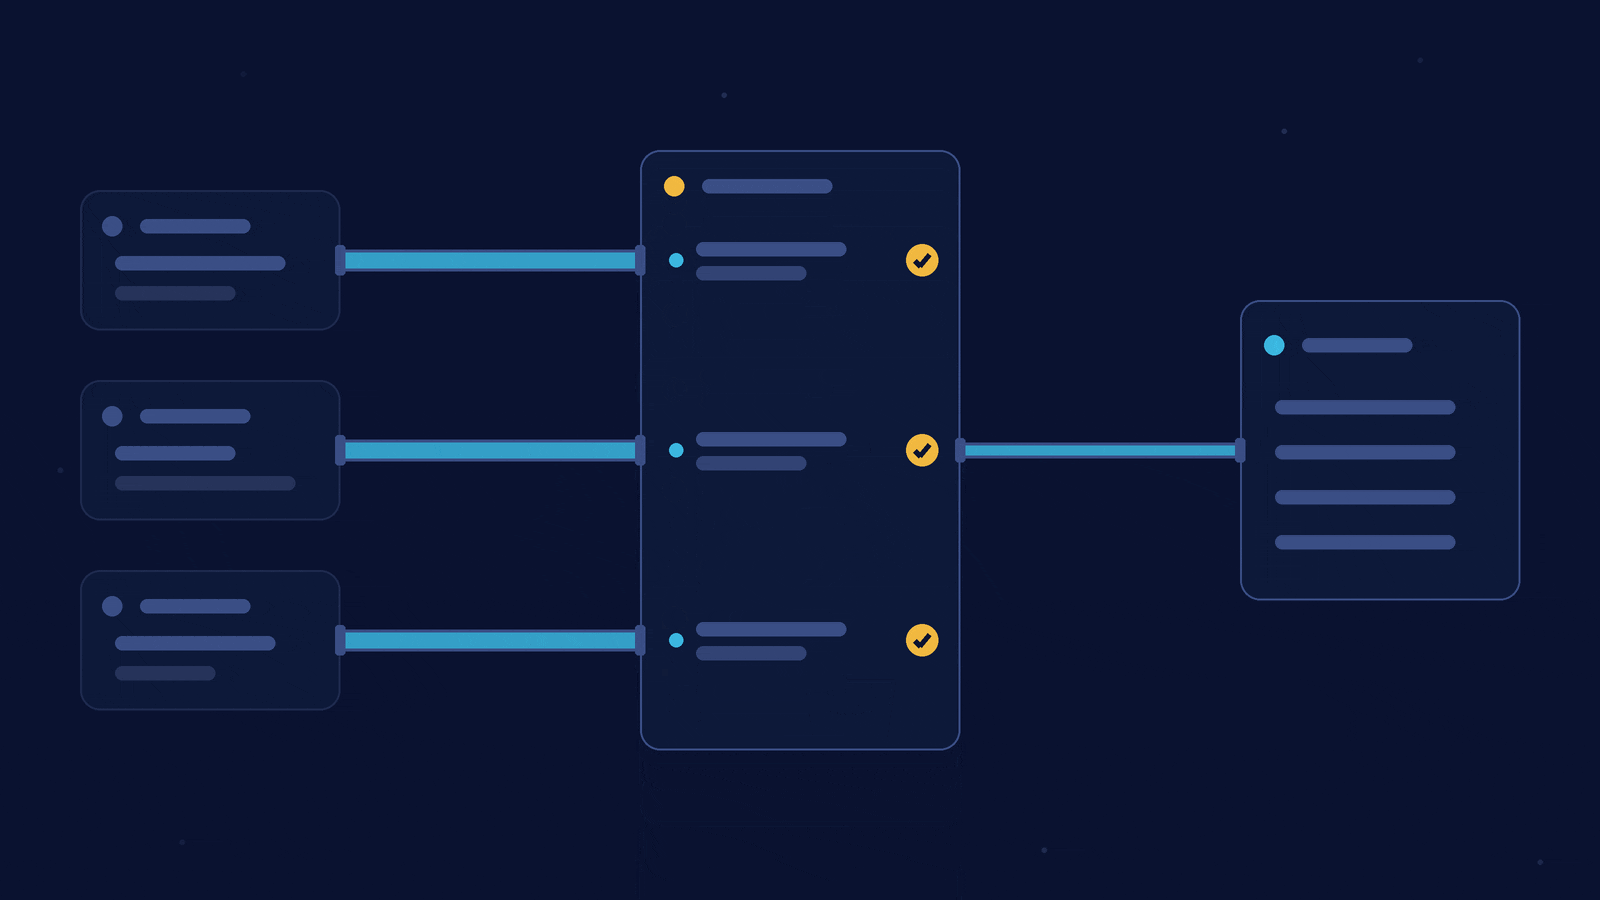
Normalize carrier schemas

Reconcile tracking formats across all carrier platforms into a unified shipment event model with standardized status codes.

Transform

Correlate shipment lifecycle

Link tracking events to warehouse records, building end-to-end shipment timelines with handoff traceability.

Transform

Score delivery risk

Apply ML-driven risk scoring based on historical carrier performance, weather, and route congestion signals.

6 nodesDataUnsaved changes
Belvedere AIOnline

How does the risk scoring work?

The pipeline analyzes historical delivery patterns, current weather, and real-time route congestion across all carriers. Each shipment gets a risk score from 0–100, with alerts triggered above 75.

Ask about this pipeline
app.clearfracture.ai/catalog
Live
BelvedereData Catalog
SIGINT Feed AlphaDatabase Connection
14 fields
Classification & Security
MarkingTS/SCI — Top Secret / Sensitive CompartmentedTS/SCI
DisseminationNOFORN — Not Releasable to Foreign NationalsNOFORN
Handling CaveatSpecial handling procedures apply
Access & Releasability
ReleasabilityREL TO USA ONLYUSA Only
Data OwnerSIGINT Operations Division
Access LevelAuthorized personnel — need-to-know
Topic Taxonomy
DomainSignals Intelligence / CommunicationsInferred
Content Fieldsintercept_body, metadata_header
ClassificationLLM topic classification availableAI
Source Metadata
CategoryDatabase Connection
Update Freq.Real-time / Event-driven
Quality Score92 / 100 — High confidence
Data Governance
RetentionMission-defined retention policy
PII DetectionScanned — 3 fields flaggedScanned
LineageCollector → Catalog → EnrichmentTracked
Inferred Schema
14 fields
Tintercept_idUUID
Ttimestamp_utcTIMESTAMP
Tsource_platformVARCHAR
Tintercept_bodyTEXT

Agentic discovery across your entire data landscape.

Belvedere's Knowledge Arm automatically discovers, classifies, and catalogs every data source across your environment — from cloud storage and databases to streaming feeds and legacy systems.

Each source is enriched with classification markings, access controls, topic taxonomy, governance policies, and inferred schema — capturing not just structure but what the data means, all without manual intervention.

  • Finds every source — cloud, on-prem, or air-gapped
  • Schema, classification, and governance inferred automatically
  • End-to-end lineage from ingestion to delivery
  • PII detection and releasability controls built in

Drift happens. Belvedere handles it.

Belvedere's Observability Arm monitors every pipeline and integration point in real time. When something drifts — a schema change, a quality anomaly, a broken contract — it detects the issue and diagnoses root cause automatically. High-confidence fixes are applied instantly. Lower-confidence changes are surfaced to your team for review — or run Belvedere in proposal mode, where every change requires human approval before it ships. You choose the level of autonomy.

  • High-confidence fixes applied automatically — no 3 a.m. pages
  • Low-confidence changes routed to your team for review
  • Proposal mode available — human approves every change before deploy
  • Full audit trail on every action, automatic or approved
app.clearfracture.ai/observability
Live
ObservabilityAll nominal
99.9%Health
2.1sLatency
7Auto-heals
Schema drift detected — auto-healedHUMINT Merge · 2 min ago
Latency spike above thresholdIdentity Graph · 8 min ago
New source column discoveredGEOINT Ingest · 15 min ago
7 auto-resolved
0 manual actions

Three Intelligent Arms. One Unified Platform.

Belvedere operates as a multi-agent system with three intelligent “arms” — knowing, doing, and watching. Processing logic is maintained separate from its implementation, making understanding accessible to non-developers and platform migrations painless.

01 — Knowing

Knowledge Arm

Continuously explores your systems, tools, and data sources to understand where data lives, what it means to different teams, how it flows, and what governs it. Definitions, relationships, and context are stored — so knowledge persists even when people leave.

  • Auto-discovers sources and schema
  • Maps lineage, context, and governance
  • Living knowledge graph of your environment
02 — Doing

Workflow Arm

Designs, tests, and deploys deterministic, auditable pipelines with enforced contracts between data producers and consumers. Context carries through every transformation layer — traceable, affordable at scale, and already trusted by the enterprise.

  • Generates deterministic, auditable code
  • Deploys on your existing infrastructure
  • Goal-oriented — declare what, not how
03 — Watching

Observability Arm

Monitors every pipeline, data product, and integration point in real time. When something drifts — a schema change, a definition that no longer matches its contract, a data quality anomaly — Belvedere detects it, diagnoses the root cause, and self-heals before it impacts downstream consumers.

  • Real-time pipeline health monitoring
  • Automatic schema-drift detection and repair
  • Self-healing with full audit trail

Give Your Existing Agent Swarm a Chief Data Officer.

Connect to the stack you already run

Belvedere works inside your existing enterprise and agent architecture, so value increases without a rip-and-replace program.

Give every agent shared, governed context

Clean data products, contracts, and lineage-aware context stay intact across transformations instead of being lost in prompts and pipeline code.

Make every agent output easier to trust

Auditable, verifiable outputs give your teams the confidence to use agent-driven decisions in real operational workflows.

Belvedere does not ask you to replace the agents, models, or orchestration layers you've already deployed. It operates inside that environment as the trusted data and governance layer, giving every agent access to current, structured, lineage-aware context instead of brittle prompts, stale retrieval results, or disconnected source systems.

Belvedere can act as the Chief Data Officer for your agent swarm, giving every agent the equivalent of a team of data engineers and data stewards. It publishes clean data products, contracts, and governed context that agents can use directly, so their decisions are informed by context that is data-driven, auditable, and verifiable. Let Belvedere operate autonomously where confidence is high, and require human review where the stakes are higher.

Verifiable by design. AI speed and intelligence, with deterministic results you can trust.

No hallucinations

Deterministic, verifiable code output — not probabilistic guesses

No vendor lock-in

Portable pipeline logic that runs anywhere your infrastructure lives

Automation you can trust

Every action is logged, explainable, and fully auditable

Operates your tools

Maximizes your existing IT investments instead of replacing them

Belvedere operates your tools on your behalf — its agents never touch mission data directly. They write verifiable code that runs inside your environment, using data contracts and system models to know what the data means before they act. No hallucinations. No black boxes. AI that produces deterministic, auditable, repeatable output you can verify before it ever reaches production.

Ready to See Belvedere in Action?

We'll show you Belvedere operating on a live data environment — not slides. See how declarative data ops delivers trusted results in minutes.

From the Clear Fracture Team

Did Prediction Markets See the 2026 Results Coming?

Did Prediction Markets See the 2026 Results Coming?

Scott FincherScott Fincher3 min readCase Studies

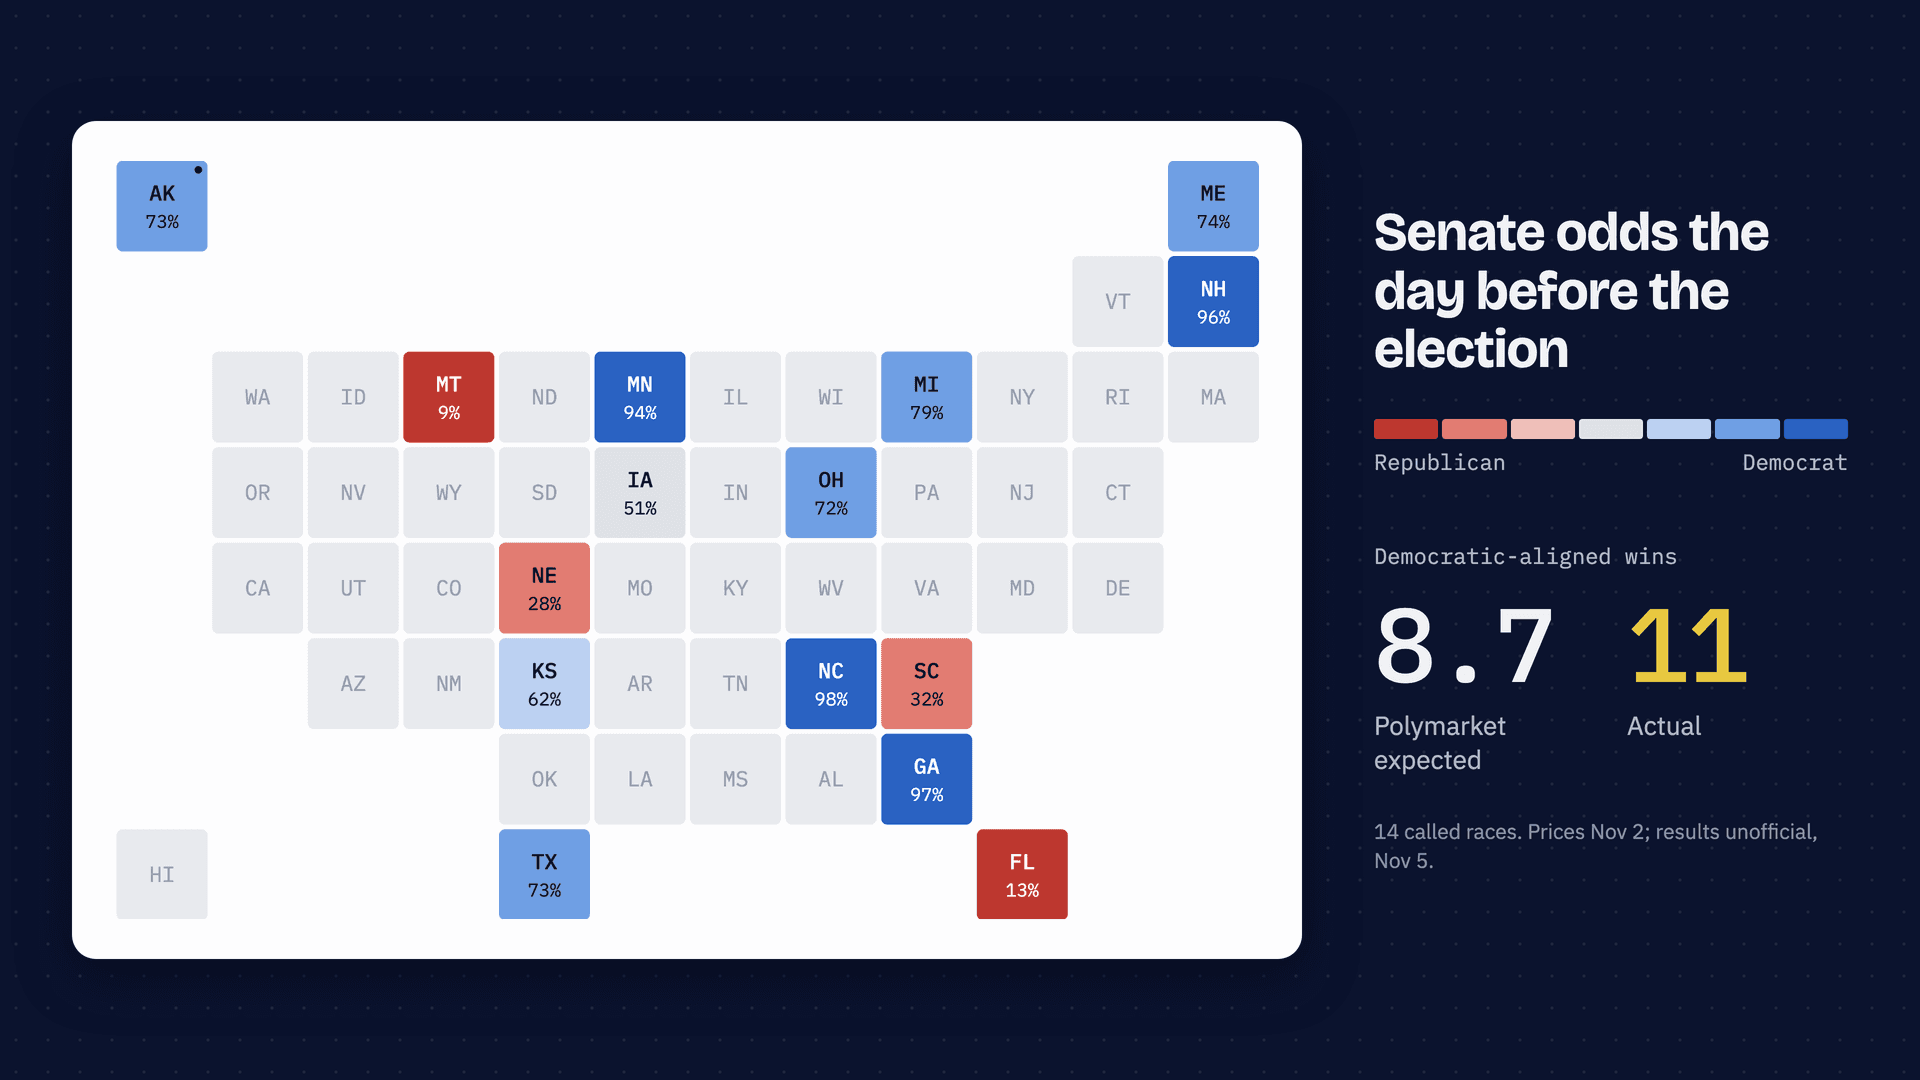
Prediction markets are the newest tool in election forecasting. More than $21 million was traded on Polymarket's Texas Senate market alone. A contract pays $1 if its candidate wins and nothing otherwise, so a 74-cent price means about a 74% chance.

In theory, traders with money on the line pay closer attention than anyone. The 2026 midterms let us test that by checking daily Polymarket prices and poll averages against the results. To dig into the data yourself, explore the Senate and governors' races in the Midterm Forecast Ledger.

We should say up front that we aren't political scientists or statisticians, just interested observers who like data.

What we found

Polls missed, and mostly in one direction. In 30 Senate and governor races with a prediction market and at least five recent polls, the final poll average underestimated the Democratic candidate in 25. On average, Democratic candidates ran about 3.5 points ahead of their polls.

That gap shrank as Election Day approached but never closed. It was almost 6 points 90 days out, 5 a month out, about 4 a week out and 3.5 the day before. Prediction markets drifted at about the same pace. Across all 67 resolved Senate and governor markets on Polymarket, prices implied about 35 Democratic-aligned wins 90 days out and 39 the day before. The actual number was 42.
How Good Are the New AI Weather Models? We Checked a Summer of Forecasts

Scott FincherScott Fincher5 min readCase Studies

At Belvedere Labs we spend a lot of time trying out new AI capabilities, wherever they show up. Weather caught our eye because it makes an unusually clean test. The forecasts are public, the answers arrive a few days later from official thermometers and rain gauges, and two of the world's biggest forecasting agencies now run an AI model alongside their traditional one.

So we gathered the forecasts four models made for eight US cities from July to October 2026 and compared each one with what actually happened. This article is a short summary of what we noticed. The full data set lives in our interactive forecast explorer, where you can dig into any city, day or model.

Two Ways to Predict the Weather

Traditional forecasts come from physics. The model splits the atmosphere into millions of 3D boxes and applies the equations for air movement, heat and moisture, stepping forward a few minutes at a time until it reaches next week. That takes a supercomputer. We looked at the two best-known examples: IFS from the European centre ECMWF, and GFS from the US agency NOAA.

AI models take a different route. They are neural networks trained on decades of past weather, and they learn how the atmosphere tends to change over six hours. Repeating that step gets them a week or more ahead. Training one takes a lot of computing, but running it is far cheaper than running a physics model. ECMWF estimates its AI model uses about 1,000 times less energy per forecast, and Google DeepMind reported that its GraphCast model produces a 10-day forecast in under a minute on a single machine. The AI models still start from today's weather as measured and prepared by the traditional systems, so the two approaches work together. ECMWF made its AI model, AIFS, operational in early 2025, and NOAA followed later that year with AIGFS, which builds on GraphCast.

Data Plumbing Isn’t Sexy. Neither Is Waiting for Intelligence.

Data Plumbing Isn’t Sexy. Neither Is Waiting for Intelligence.

Nancy DillmanNancy Dillman5 min readData EngineeringPublished October 6, 2026

When I became a CIA operations officer, I wasn’t thinking about data pipelines.

I was thinking about people, information, and the mission. About understanding what was happening and getting the right information to the people who needed it.

But somewhere behind every useful piece of intelligence was a less glamorous reality: someone had to get the information collected, processed, connected, and delivered.

Nobody puts that part in the movie.

They probably should. Although “We finally resolved the schema mismatch” would be a difficult line to build a trailer around.

The People Behind the Information

In the field, I relied on talented people to help get me good information. I was fortunate to have them.

They needed reliable ways to ingest and prepare data so analysts could connect the dots and mission teams could act. That meant more than getting information quickly. It meant preserving context, understanding where it came from, and having confidence in what it actually told us.

A useful connection buried in an inaccessible system was still buried. Information that arrived after a decision had been made couldn’t inform that decision.

The people behind that work made an enormous difference. Often, their effort was invisible precisely because they made things work.